guide
Is Seasonal Color Analysis Backed by Real Science? An Evidence Map
What color-perception research supports, what seasonal styling merely organizes, and what has not been validated about the 12-season system.
Seasonal color analysis combines a real perceptual problem with a consumer-friendly classification. Those are not equally established.
Colors around a face can change how that face is perceived. But moving from that observation to “every person belongs to exactly one of twelve seasons” adds conventions, thresholds, and human judgment that have not been standardized across the industry.
Quick answer
- Strong foundation: color appearance depends on context, including surrounding colors and illumination.
- Relevant but limited evidence: controlled studies can find systematic preferences for clothing colors beside photographed faces.
- Practical convention: warm/cool, light/deep, and soft/clear axes are useful ways to organize comparisons.
- Not established as a universal diagnostic: one fixed twelve-season taxonomy, standardized category thresholds, or a universally accepted accuracy test.
A season result can be useful without being a scientific diagnosis. The honest standard is to keep those claims separate.
Evidence-strength map
| Claim | Details |
|---|---|
| Surrounding colors affect appearance | Evidence level: Strong color-perception foundation; What the evidence supports: Context can shift perceived lightness, hue, or contrast; What it does not establish: Which fashion color is objectively “best” for one person |
| Clothing color choices vary with visible skin appearance | Evidence level: Direct but limited research; What the evidence supports: Group-level preferences can be measured in controlled image studies; What it does not establish: A complete rule for all skin tones, cultures, settings, or materials |
| Temperature, value, and chroma are useful comparison dimensions | Evidence level: Established color-description concepts; styling application is interpretive; What the evidence supports: A transparent vocabulary for comparing color samples; What it does not establish: Universal seasonal boundaries |
| Four or twelve seasons are the correct natural categories | Evidence level: Weak/direct validation not located; What the evidence supports: A memorable way to organize styling hypotheses; What it does not establish: A biological or clinical classification |
| A consultant or photo tool can identify a season with known accuracy | Evidence level: Method-dependent; What the evidence supports: A repeatable result is possible when a method is defined; What it does not establish: A universal accuracy percentage without a shared reference standard |
The part grounded in color perception
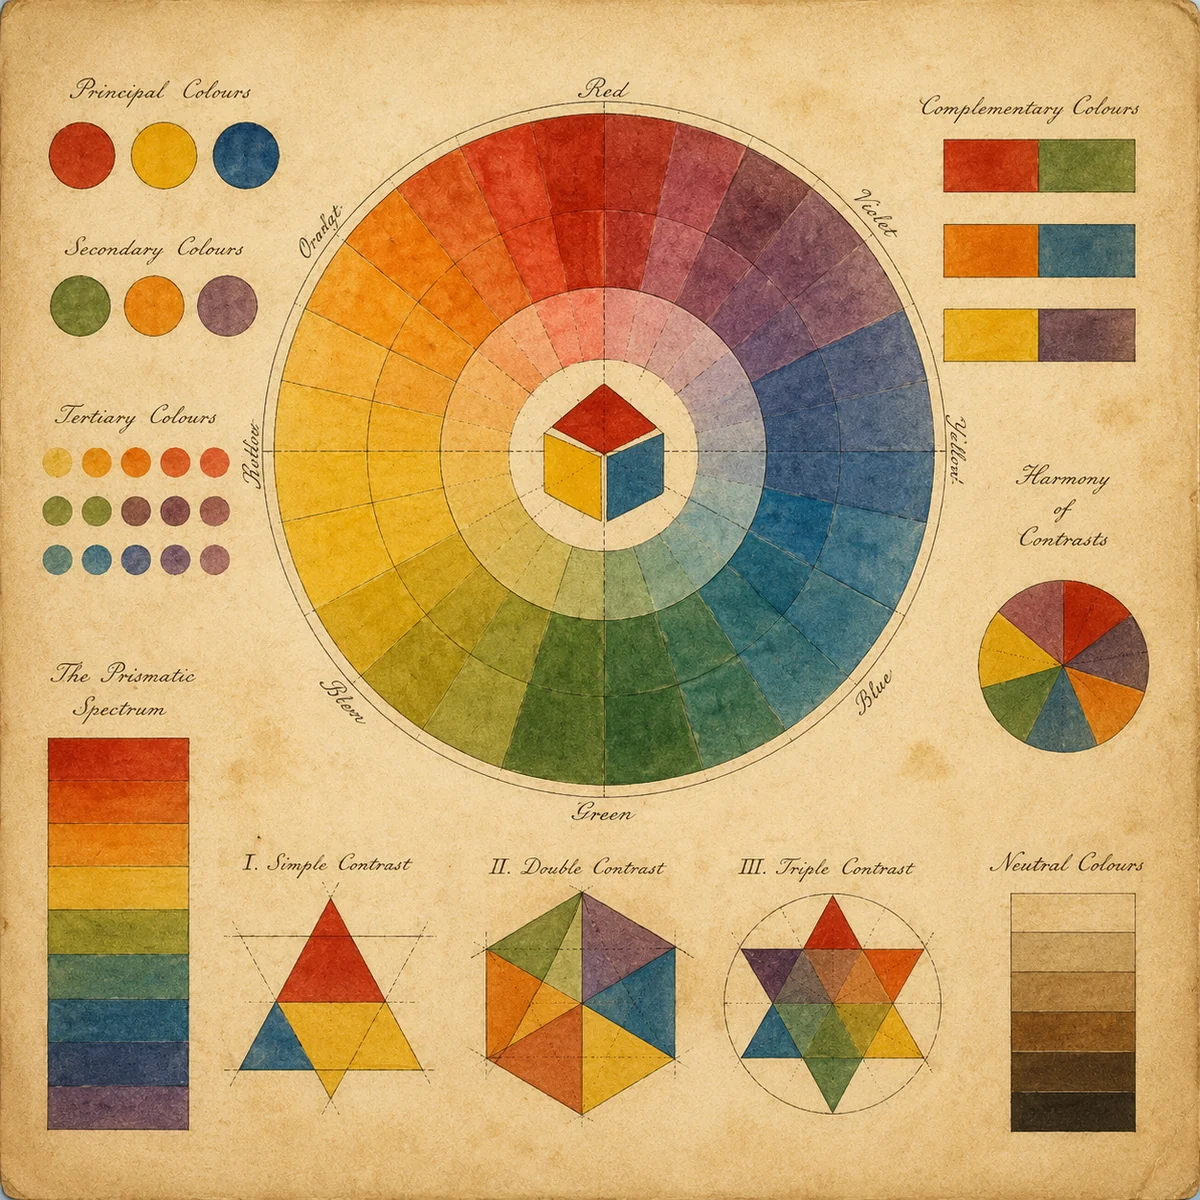
Michel Eugène Chevreul’s nineteenth-century work described how adjacent colors alter one another’s appearance. The historical text is available in the Project Gutenberg archive. Chevreul studied color relationships and practical arts—not personal beauty seasons—but the contextual principle is relevant.
Modern color-appearance science goes far beyond Chevreul, accounting for illumination, adaptation, surroundings, and viewing conditions. The core caution for at-home analysis follows directly: a shirt color cannot be evaluated independently of lighting and context.
That does not mean a garment physically changes skin or proves a physiological benefit. It means the visual system judges colors relationally.
What direct clothing-and-skin research shows
Perrett and Sprengelmeyer’s 2021 i-Perception study tested clothing-color choices beside images of faces with fair and tanned skin appearances. Participants made systematic choices; for example, many selected clothing with a higher CIE b* (more yellow) direction for tanned than fair versions of the faces.
That is useful evidence that clothing/face color relationships can be studied rather than merely asserted. It is still narrow:
- it concerns specific manipulated images and participant choices;
- a preference judgment is not the same as a universal rule;
- fair-versus-tanned appearance is not the full range of human skin color;
- the study does not validate Spring, Summer, Autumn, Winter, or twelve subtypes.
The correct conclusion is smaller than “seasonal color is proven,” but stronger than “all color matching is imaginary.”
Where season labels come in
Seasonal terminology became popular in consumer styling literature, including Carole Jackson’s Color Me Beautiful in 1980. The four labels provided a memorable way to package warm/cool and related visual differences. Later systems expanded the model into twelve or more subtypes.
The exact modern taxonomy is not controlled by one standards body. Systems may rename True Spring as Warm Spring, split categories differently, or introduce terms such as Soft Spring that are absent from EverlySpark’s declared twelve-season map.
For the comparison method and its limits, see our methodology guide.
What remains unvalidated
During this review, EverlySpark did not locate a broad peer-reviewed validation demonstrating all of the following together:
- a shared reference standard for assigning one of twelve seasons;
- reliable agreement among analysts using that standard;
- accuracy across varied skin colors, ages, hair colors, cameras, and lighting;
- proof that twelve categories predict preferred outcomes better than simpler or continuous alternatives.
This is a search finding, not proof that no such research exists. The review was targeted rather than a formal systematic review.
A 2026 ACM conference paper, Lumina, illustrates both momentum and limits in automated seasonal classification. It used explainable machine learning on an existing seasonal-color dataset, yet the reported per-class performance varied substantially; the paper reports Spring recall of 0.39 for its model and discusses a prior deep model at 55.4% accuracy on the cited dataset. These results are research prototypes, not consumer accuracy guarantees.
Hard mechanism, soft categorization
The most defensible summary is:
Context-dependent color appearance is the hard mechanism. Seasonal classification is a soft organizational layer.
That layer may still help. A wardrobe shortlist does not need to be a biological truth to reduce choices. Problems begin when a styling label is presented as if it were an objective diagnosis, or when a tool’s internal score is described as measured real-world accuracy.
How to test a claim rather than trust it
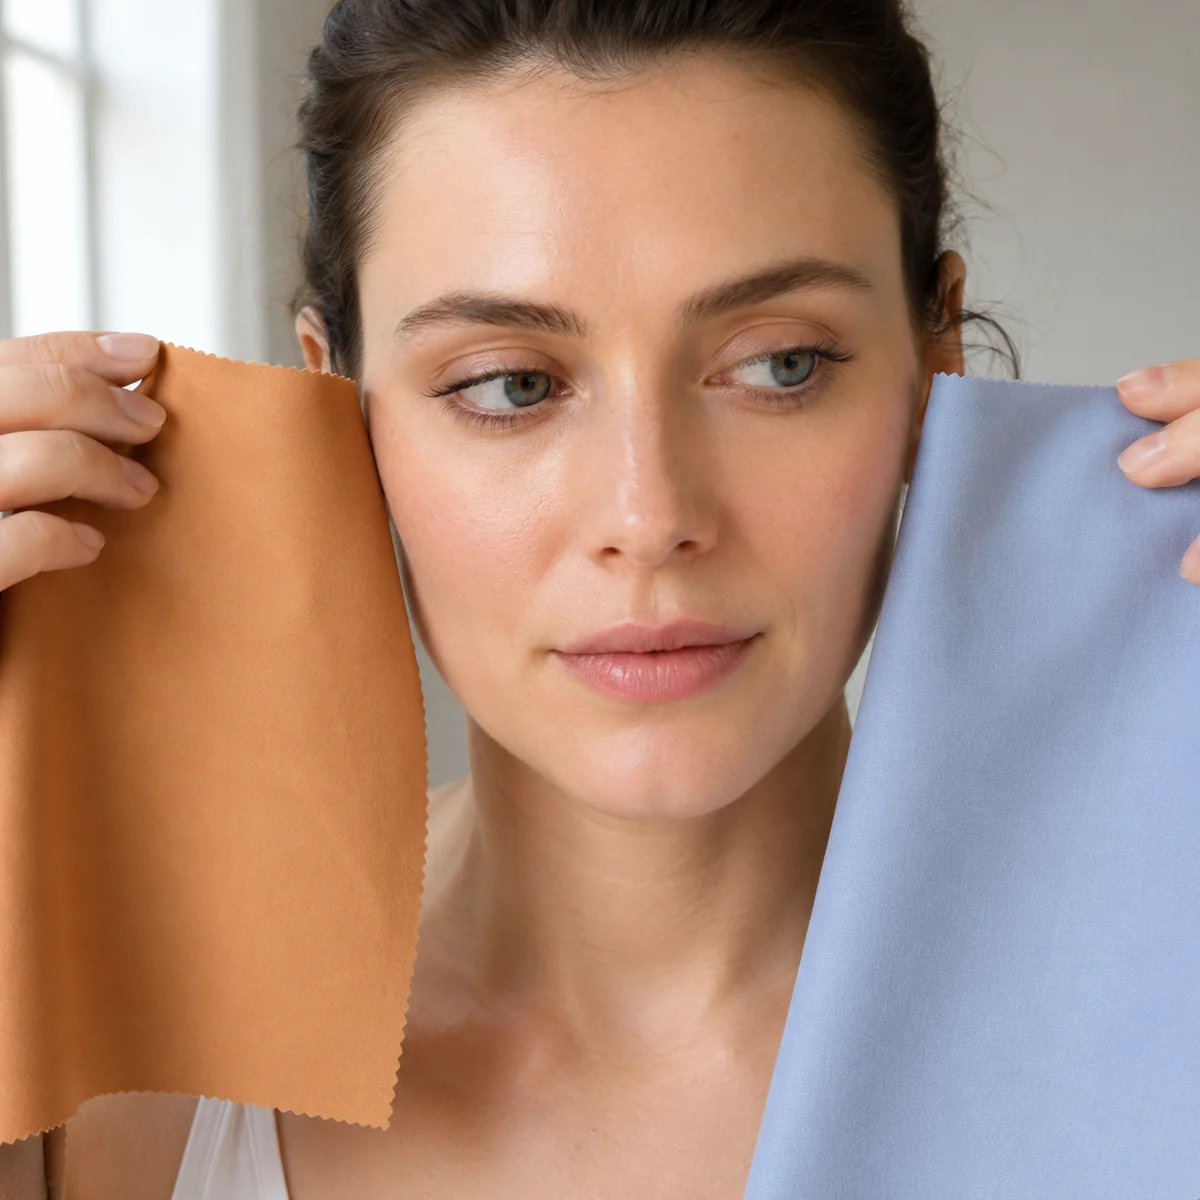
Use a controlled pair:
- Choose two versions of the same hue that differ mainly on one axis.
- Keep lighting, camera, distance, expression, and fabric area fixed.
- Compare the face, not which fabric you prefer.
- Repeat with at least two more pairs testing the same axis.
- Record when the result reverses or becomes ambiguous.
A repeatable pattern across multiple pairs is more useful than a season quiz based on veins, a single selfie, or one piece of jewelry. Our best-colors matrix converts the four axes into testable color versions.
Where EverlySpark’s analyzer fits
EverlySpark’s photo-based analyzer samples visible colors from a photo in the browser and applies fixed rules. It does not run an AI model, diagnose a condition, or carry an independently established accuracy percentage.
The output is a hypothesis affected by the photograph. White balance, exposure, colored reflections, makeup, dyed hair, and sampling placement can change the input. Use the result to choose two or three candidate palettes, then test real colors in stable light.
Unanswered questions worth asking
A stronger evidence base would need to answer:
- How consistently do trained analysts agree under the same lighting and drapes?
- Which outcome is being optimized: observer preference, self-preference, face visibility, purchase satisfaction, or something else?
- Do categorical seasons outperform continuous scores for temperature, value, and chroma?
- How do results change across skin colors and different cultural preferences?
- How much of a result comes from the face, and how much from hair, makeup, background, or camera processing?
Until those questions are better answered, certainty should stay proportional to the evidence.
Research method and source boundaries
This article was updated on September 7, 2026 using a targeted source review. Preference order was: primary historical text, peer-reviewed research, research proceedings, and authoritative bibliographic records. Search terms covered simultaneous color contrast, clothing color and skin appearance, seasonal color validation, and automated seasonal classification.
The review is not a systematic review and does not claim exhaustive coverage. Statements about how EverlySpark organizes the axes are EverlySpark editorial methodology, not findings attributed to the external studies.
Sources
- Michel Eugène Chevreul, The Laws of Contrast of Colour, Project Gutenberg archival edition. Historical primary source; not a personal-color study.
- David I. Perrett and Richard Sprengelmeyer, “Clothing Aesthetics: Consistent Colour Choices to Match Fair and Tanned Skin Tones,” i-Perception 12(6), 2021. Peer-reviewed.
- “Lumina: Seasonal Color Analysis System with Explainable Machine Learning,” ACM IAIT 2026 proceedings. Emerging computational research; not independent validation of consumer tools.
- WorldCat record for Color Me Beautiful / later edition. Bibliographic and publishing context, not scientific validation.
FAQ
Is seasonal color analysis scientifically proven?
Not as one complete twelve-category diagnostic. Context-dependent color appearance is well grounded, and some controlled research addresses clothing-color preferences beside faces. The season taxonomy and its boundaries have much weaker direct validation.
Does that make the system useless?
No. It can be a practical shortlist. Use the label to generate comparisons, then let repeatable real-world observations decide.
Can two analysts disagree?
Yes. Without a single reference standard and universal thresholds, different methods can classify a boundary case differently. Ask for the observed axis pattern, not only the label.
Is a photo tool equivalent to draping?
No. The analyzer section above explains the differences; draping lets you compare fabrics in real time. Both still involve method choices and interpretation.